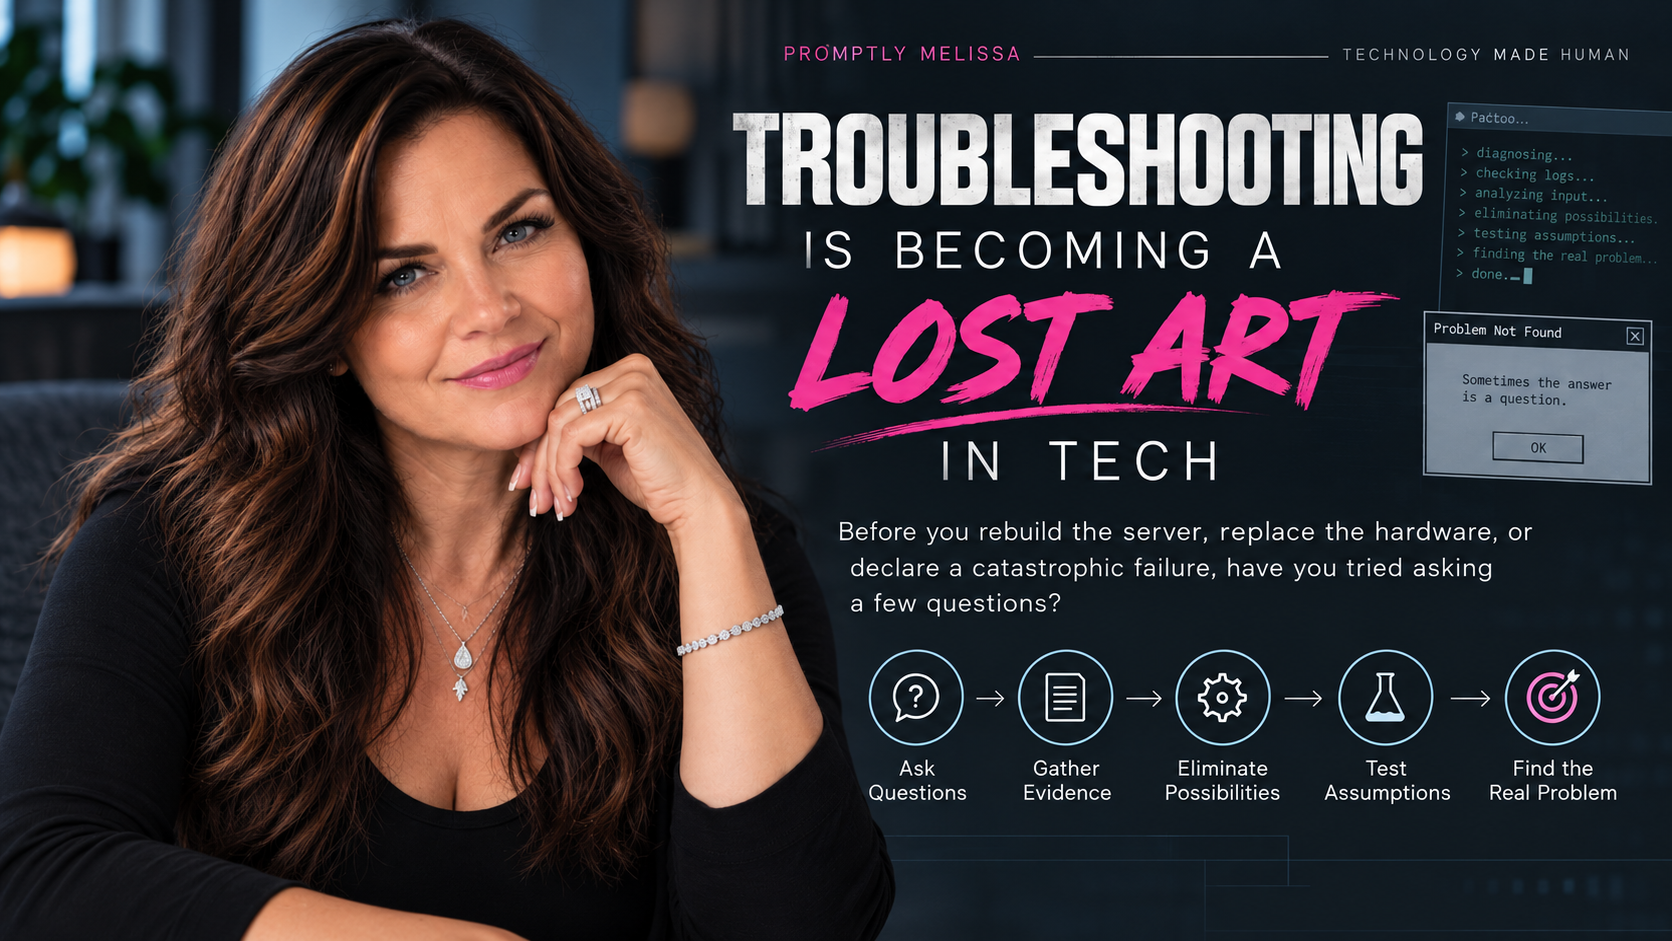
Troubleshooting Is Becoming a Lost Art in Tech
Before you rebuild the server, replace the hardware, or declare a catastrophic infrastructure failure, have you tried asking a few questions?
Technology complicated things that used to be simple.
And that’s wonderful. Really.
I remember spending hours reinstalling Windows from a CD-ROM, only to have Setup fail at 90% because the disc had a scratch. Today, I can download a fresh installation image instead of waiting two weeks for Microsoft to mail me a replacement.
Progress is good.
But somewhere along the way, I started noticing something that concerns me: people can learn how to operate technology without necessarily learning how to troubleshoot it.
And those are two very different skills.
Troubleshooting Is Not Magic
I’ve spent roughly 30 years working in IT. I’ve worked in technical support, infrastructure, systems administration, and documentation. I’ve watched technologies come and go, operating systems evolve, and entire categories of IT work transform.
One thing has remained remarkably consistent.
When I’ve trained new technicians, I’ve often explained troubleshooting the same way:
Troubleshooting is asking questions and following a process of elimination.
That’s it. That’s the secret.
You don’t have to know the answer before you begin. You have to know how to investigate the problem without letting your assumptions get ahead of the evidence.
What exactly isn’t working?
When did the problem start?
Is it affecting one user or everyone?
Does it happen in one application or across the entire computer?
What changed before the problem appeared?
Can you reproduce the error?
Each answer gives you another piece of information. Each piece of information helps you eliminate possibilities and narrow down the cause.
You form a hypothesis, test it, observe the result, and adjust your thinking accordingly.
That’s troubleshooting.
It’s also the scientific method wearing a company-issued polo shirt.
Start With the Power Cord, Not Disaster Recovery
I’ve seen enough IT problems to know that the apparent severity of a complaint doesn’t necessarily tell you anything about the actual cause.
A user reports that the network is down. Someone starts investigating switches, routing, DNS, authentication, and infrastructure dependencies.
Meanwhile, the network cable is unplugged.
Congratulations. We’ve nearly convened a disaster recovery committee to resolve a loose cable.
It sounds ridiculous, but the principle is important: start with the simplest plausible explanations and work toward more complex ones as the evidence warrants it.
Check the basics. Establish the scope. Gather information. Test your assumptions.
Don’t rebuild Active Directory because one user can’t log in. Don’t reinstall Windows because one application crashes. Don’t replace hardware until you’ve established that the hardware is actually the problem.
Of course, some incidents require immediate containment or emergency action. You don’t casually investigate a suspected security breach while an attacker continues operating in your environment.
But even then, you need a methodical approach. Urgency is not an excuse for guessing.
The goal isn’t to choose the easiest explanation. It’s to find the explanation that fits the evidence with the least unnecessary disruption.
The Error Message Is a Clue, Not a Diagnosis
Anyone who has worked with technology long enough has encountered an error message that seems to have been written by someone who actively dislikes humans.
Sometimes the message tells you exactly what failed but provides very little insight into why. Sometimes it points toward a symptom rather than the underlying cause. And sometimes the message is so vague that you have to investigate the surrounding circumstances to understand what’s happening.
This is why experienced technicians learn to look beyond the message itself.
What was the user doing when the error occurred?
Does it happen consistently?
Can you reproduce it on another machine?
Are there related events in the logs?
Did anything change immediately before the problem began?
Back when I worked on a Level 2 support desk, we had a lab where we could attempt to reproduce problems that Level 1 couldn’t resolve. We investigated the symptoms, tested possible causes, and tried to determine what was actually happening.
It wasn’t always quick. Sometimes the problem was intermittent. Sometimes it took hours to isolate the conditions that triggered it.
But reproducing an error gave us something concrete to investigate instead of relying on guesses.
And that’s why I built little VBScript applications for the help desk. They prompted technicians to gather the information Level 2 needed before escalating a ticket.
Which operating system? Which service pack? Which version of Internet Explorer? What application was involved? When did the problem begin? What had changed? What troubleshooting had already been performed?
The point wasn’t to make technicians fill out paperwork for the sake of paperwork. It was to collect useful evidence before the ticket landed on somebody else’s desk.
A ticket that says “Application broken” isn’t much help.
A ticket that describes the application version, the exact steps that trigger the error, the resulting message, and the troubleshooting already attempted gives the next technician a place to start.
Good troubleshooting begins with good questions. Good escalation begins with good documentation.
Automation Is Wonderful. Until You Don’t Understand What It Automates.
I’m not arguing that we should return to the days of manually installing operating systems from scratched CDs. I have absolutely no desire to recreate that experience.
Modern tools have made an enormous amount of work faster, safer, and more consistent. Automation can eliminate repetitive tasks, reduce human error, and allow IT professionals to manage systems at a scale that would once have been impossible.
Cloud platforms abstract away complexity so administrators don’t have to manage every underlying component themselves.
That’s a good thing.
But abstraction has a downside when people mistake not having to manage a component for not needing to understand it.
For example, managing users in Microsoft Entra ID is not the same thing as understanding Active Directory Domain Services. The technologies are related, but they have different architectures, capabilities, and failure modes.
Knowing how to navigate a cloud administration portal doesn’t automatically teach you how to diagnose a traditional domain controller, understand directory replication, investigate DNS failures, or recover a damaged infrastructure component.
You don’t need to be an expert in every underlying technology to use a modern platform effectively. Nobody could reasonably know everything.
But when your responsibilities include troubleshooting complex failures, you need enough understanding to investigate the systems you’re responsible for.
An interface can make a task easier without eliminating the need to understand what you’re doing.
And when an automated process fails, knowing what happens underneath the interface can make the difference between a quick recovery and hours of unnecessary work.
You Can’t Learn Troubleshooting by Memorizing Fixes
There’s a difference between knowing a collection of troubleshooting steps and understanding how to troubleshoot.
A technician might memorize that restarting a service resolves a particular error. That’s useful knowledge.
But what happens when restarting the service doesn’t work? What if it works temporarily and the problem returns? What if the service is failing because of a dependency, a permissions issue, a configuration change, or a resource constraint?
The memorized fix has reached its limit.
Troubleshooting requires you to ask why the fix worked, why it failed, and what the results tell you about the underlying problem.
This is one reason hands-on experience matters so much. Working through real incidents exposes you to unexpected behavior, incomplete information, conflicting symptoms, and problems that don’t match the examples in a training guide.
On a service desk, you encounter a steady stream of problems. You learn to distinguish common failures from unusual ones. You learn which questions reveal useful information. You learn when to keep investigating and when to escalate.
You also learn humility.
Sometimes the complicated problem really is complicated. Sometimes the obvious solution is correct. And sometimes you spend an hour investigating an issue before discovering that the device was unplugged.
It happens. You document the resolution, learn from it, and move on.
The goal isn’t to avoid looking foolish. The goal is to solve the problem.
Experience Teaches You What Not to Do
One of the most valuable lessons in IT is learning when to leave something alone.
A proposed fix might resolve the immediate symptom while introducing a larger problem. Reinstalling an operating system might restore a workstation, but it could also destroy useful diagnostic evidence or remove configurations that someone needs.
Making changes to a production environment without understanding the potential consequences can turn a minor incident into a major one.
Experienced technicians learn to consider the risks of an intervention before applying it.
Can I test this safely?
Can I reproduce the problem?
Is there a less disruptive way to isolate the cause?
Do I have a rollback plan?
What evidence will tell me whether this change actually fixed the problem?
This doesn’t mean every minor issue needs a formal change-management meeting. It means the scope of your investigation and the risk of your actions should match the situation.
Good troubleshooting isn’t about how quickly you can change something. It’s about how efficiently you can identify the cause and make the right change.
Documentation Is Part of the Fix
Here’s where troubleshooting and documentation come together.
Imagine spending three hours reproducing an intermittent application failure, identifying the cause, and finding a reliable resolution.
You close the ticket with: “Fixed.”
Congratulations. The next technician gets to spend three hours rediscovering everything you just learned.
A useful incident record should capture the symptoms, the affected systems, the relevant timeline, the steps used to reproduce the problem, the tests performed, the findings, and the resolution.
When possible, it should distinguish the immediate workaround from the confirmed root cause.
That information becomes organizational knowledge. It helps other technicians resolve similar incidents faster, prevents unnecessary duplication of effort, and makes patterns easier to recognize across multiple incidents.
This is why knowledge bases, standard operating procedures, and well-documented troubleshooting workflows matter.
The fix gets one system working again. The documentation helps the entire organization work smarter the next time the problem occurs.
And if you discover that the same issue keeps recurring, you’ve identified an opportunity to investigate the underlying process, improve the system, or automate part of the response.
That’s how troubleshooting becomes continuous improvement instead of an endless cycle of putting out fires.
So, Is Troubleshooting Really a Lost Art?
I don’t believe every new IT professional lacks troubleshooting skills. Plenty of excellent technicians and engineers are learning these principles every day, and modern diagnostic tools give them capabilities that earlier generations could only dream about.
The problem isn’t that technology has become easier to use. That’s progress.
The problem is when organizations prioritize speed, certifications, tool familiarity, or quick resolutions without ensuring that people can investigate failures methodically.
A certification can demonstrate knowledge. A tool can automate a process. A dashboard can make a complicated system easier to manage.
None of those things automatically teaches someone how to reason through an unfamiliar problem.
That skill requires practice, curiosity, patience, and the willingness to follow the evidence even when it contradicts your first assumption.
It also requires a workplace that gives people opportunities to learn from experienced colleagues, investigate real incidents, and understand why a solution works rather than simply memorizing which button to click.
The industry doesn’t need less automation. It needs people who understand how to use automation intelligently, recognize when something has gone wrong, and investigate the failure without immediately reaching for the most drastic solution.
We need technicians who know how to ask good questions, administrators who understand the systems they’re responsible for, and teams that preserve what they learn.
Because technology will keep changing. The tools will change. The interfaces will change. The terminology will change.
But the fundamental process of troubleshooting will remain remarkably familiar.
Gather evidence. Ask questions. Eliminate possibilities. Test your assumptions. Document what you learn.
And before you rebuild the server, replace the hardware, or declare a catastrophic infrastructure failure?
Check the power cord.
Trust me. It’s worth checking.
Promptly Melissa 💻✨ | Technology Made Human
Thirty years in IT. Still annoyed. Still troubleshooting.
One Comment